ETL & Data Pipelines
Reliable, monitored pipelines that move data from every source into your warehouse or lakehouse, so reports never run on stale numbers.
What Our ETL & Data Pipelines Service Covers
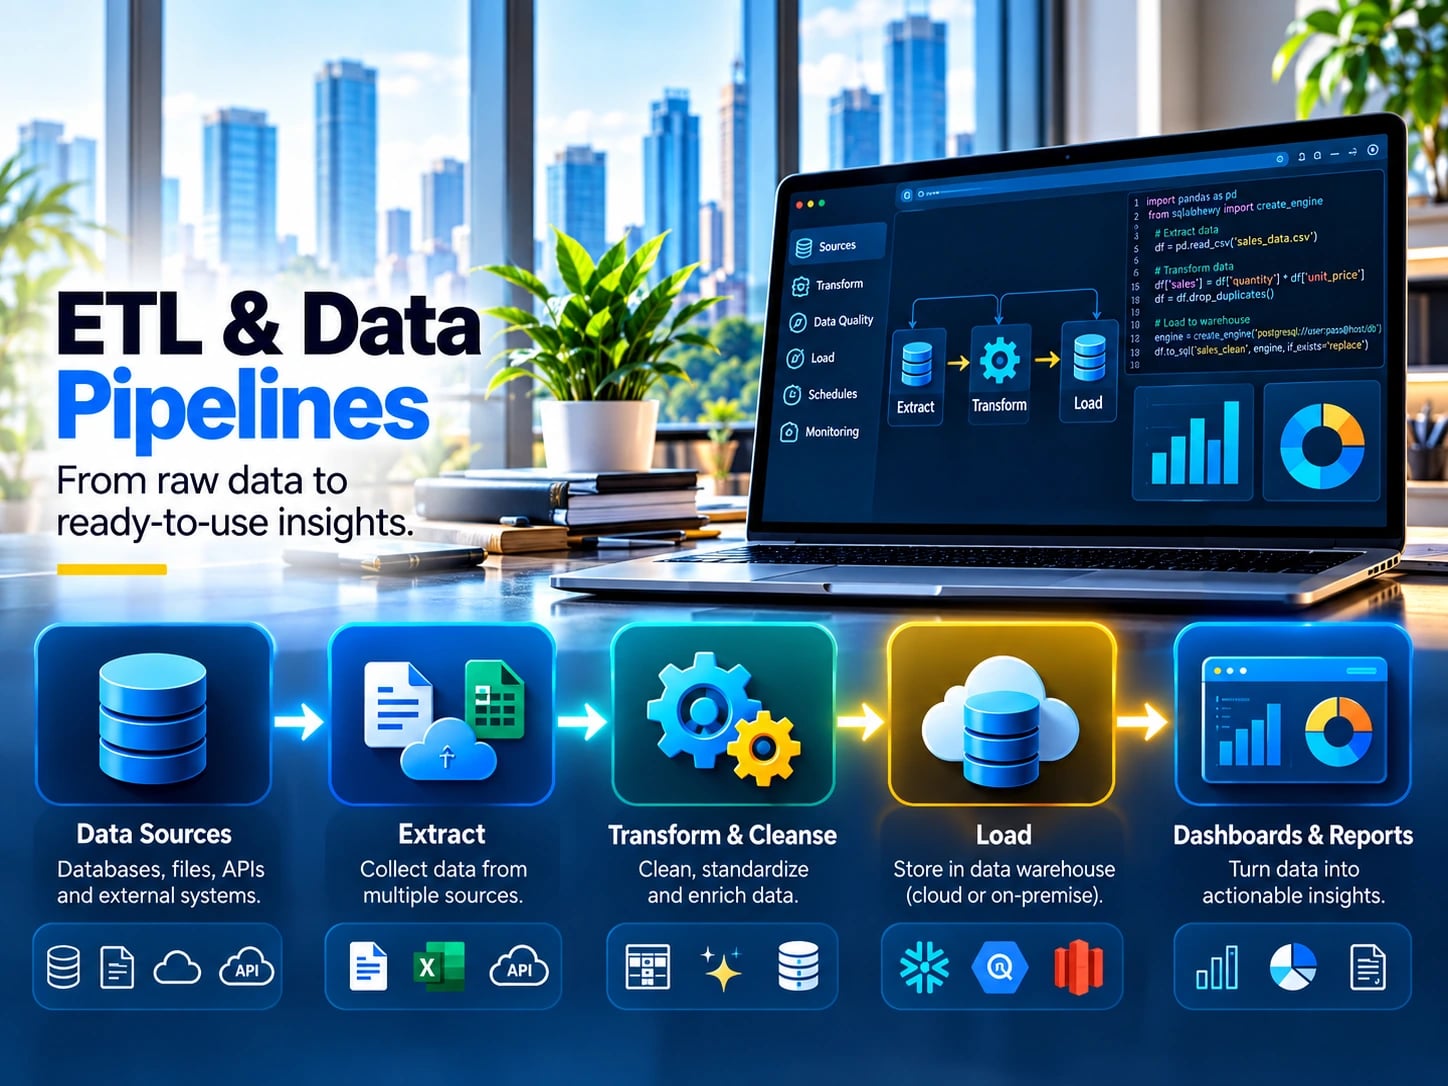
Pipelines that move data reliably from any source into your warehouse, covering REST and GraphQL APIs, production databases, scheduled flat file drops and cloud storage buckets. We build in Python and SQL, orchestrate with Airflow or Prefect, model transformations in dbt, and reach for Fivetran where a managed connector is simply the cheaper answer. On the lakehouse side we work extensively in Databricks, using Spark and Delta Lake for volumes that outgrow a conventional warehouse, with Unity Catalog governing access and lineage across the estate. Every pipeline is idempotent, version controlled and monitored, with retries, alerting and failure messages a human can read. The goal is straightforward: you should never discover that a load broke by watching an empty dashboard load in a board meeting.
What's Included
Every engagement is scoped in writing, but these are the deliverables you can expect as standard.
Source connectors
Extraction from REST and GraphQL APIs, production databases, flat file drops and cloud storage buckets.
Transformation layer
Tested, documented dbt or Spark models that clean, join and reshape raw data into analysis ready tables.
Orchestration
Airflow, Prefect or Databricks Workflows schedules with dependencies, retries and backfills handled properly.
Monitoring and alerts
Freshness checks, row count tests and readable failure alerts sent to email, Slack or Teams.
Version control and CI
All pipeline code in Git with automated tests, so changes are reviewed and deployments are repeatable.
Runbook
Clear documentation of every pipeline, its owner, its schedule and what to do when it fails.
Built for Teams Like Yours
If any of these sound familiar, this service is a good place to start.
- Companies whose reports depend on manual exports
- Data teams outgrowing scheduled scripts on a single server
- Organisations moving to Databricks, Snowflake or BigQuery
- Businesses combining data from many SaaS tools
From Brief to Delivery
- 01
Map the sources
We inventory every source, its volume, its update frequency and who owns it.
- 02
Design the architecture
You approve a pipeline design covering tools, schedules, costs and failure handling before build starts.
- 03
Build and test
Pipelines are built incrementally, each load validated against the source before the next is added.
- 04
Operate and hand over
We run the pipelines alongside your team until they are stable, then hand over the runbook and access.
ETL & Data Pipelines FAQs
Should we build or buy connectors?
Where a managed connector such as Fivetran is cheaper than maintaining custom code, we recommend it. We build only where it pays off.
Do you work with Databricks?
Yes, extensively. We use Spark, Delta Lake and Unity Catalog for workloads that outgrow a conventional warehouse.
What happens when a pipeline fails?
It retries automatically, then alerts a named person with a message that explains what broke and where to look.